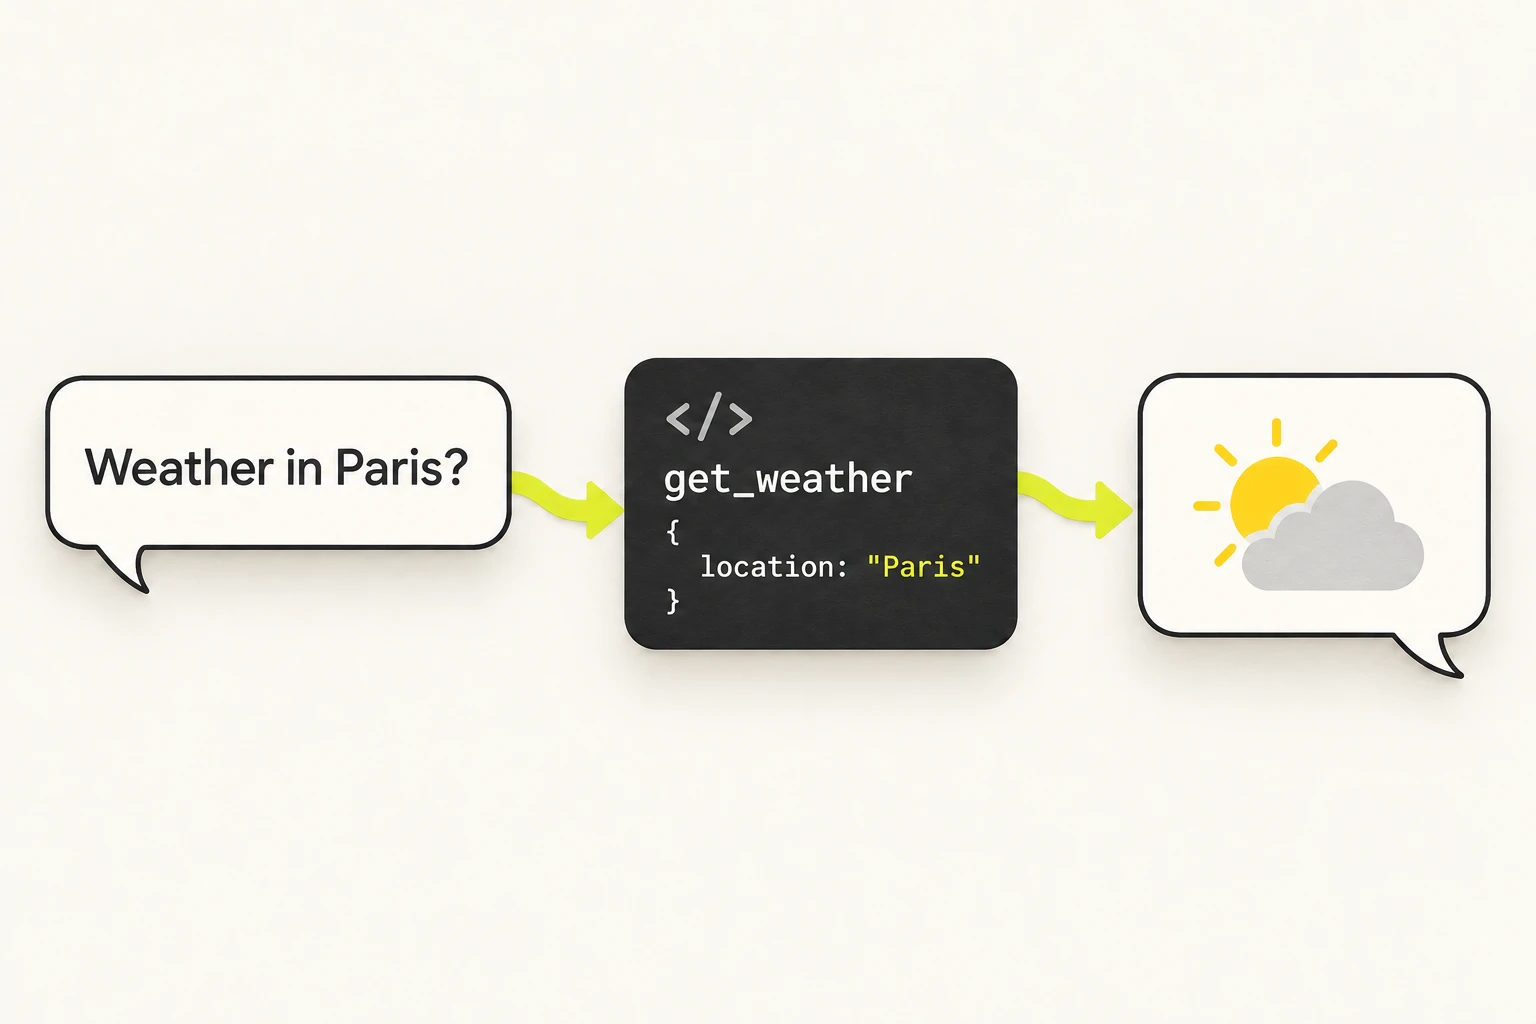
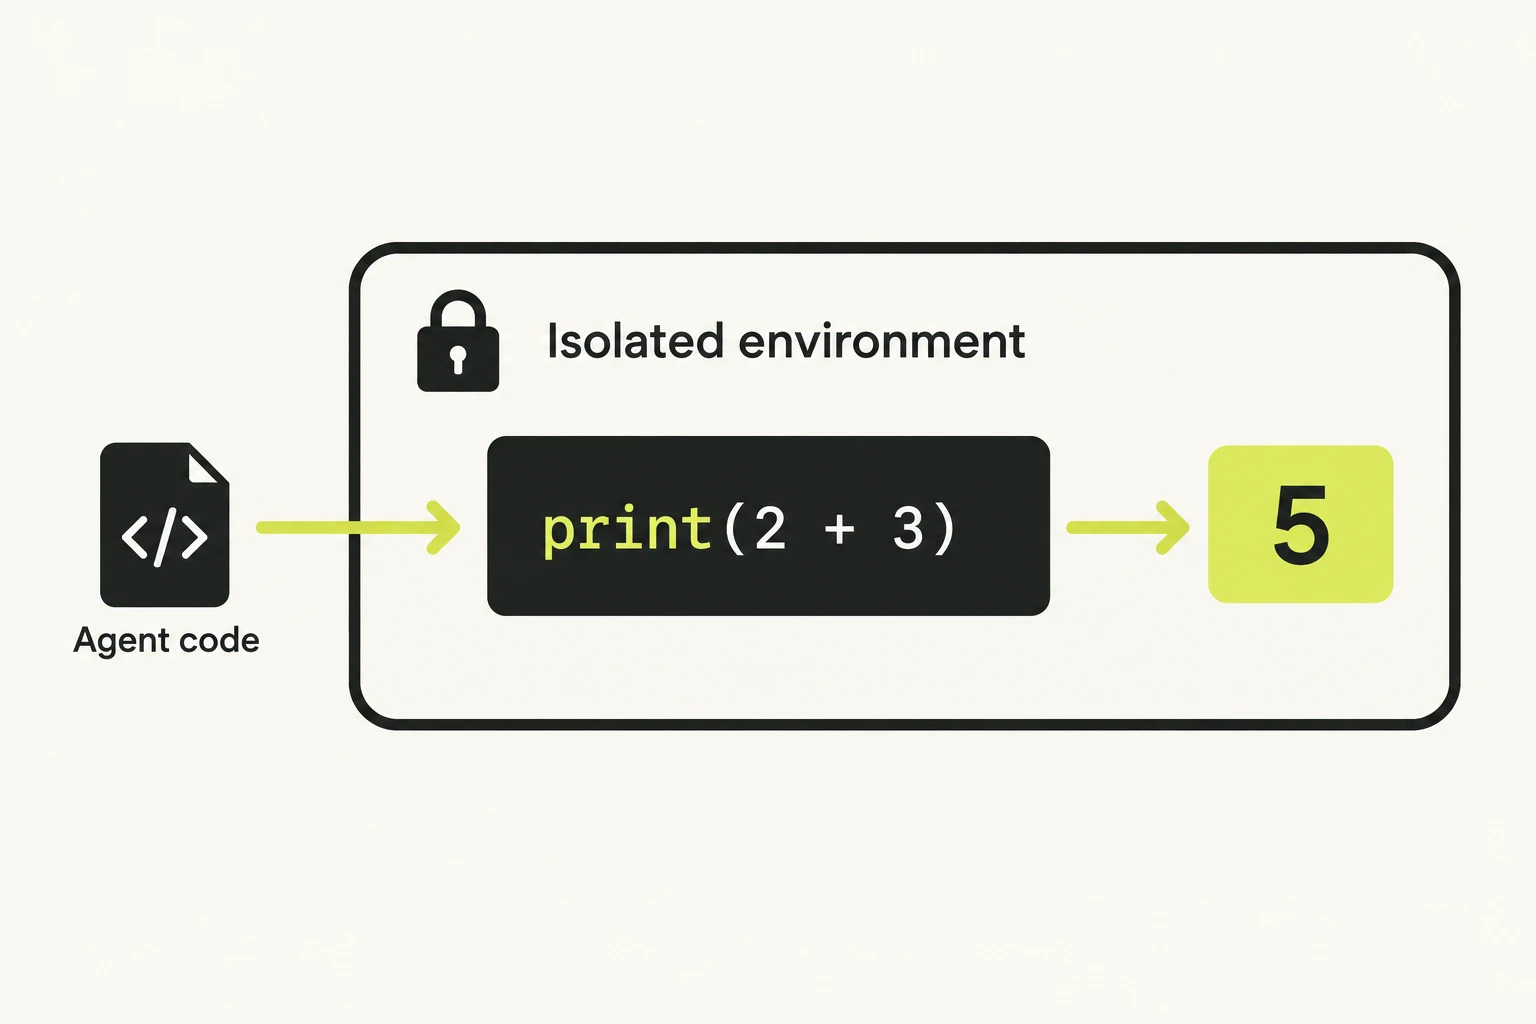
Serve your own models, process GPU batch jobs or run agent code. Start with a Python function: Blade builds the image, schedules the GPU and scales to zero. Join the waitlist to confirm your runtime and GPU requirements with the team.
Lowest From price per category. Input rates shown for token-billed models.
No subscription
No minimum spend
Rate set at submission
Track usage in the console
Everything your key does, with its price next to it.
Requests, tokens and what each one cost, key by key, in the console.
16models
328 msfastest first token
From €0.0183lowest, per 1M input tokens
€0subscription
Why the rate moves. Dynamic rates follow GPU demand. The multiplier in force when you submit a request is the one used for it, and recorded usage and charges are in the console.
console.blade.sh · Usage
UsageAPI keysModelsAI FabricBillingDocs
Illustrative usage: example requests priced at the catalogue’s From prices
Time
Model
Key
Usage
Cost
13:02:11
qwen3.6-35b-a3b
support-agent
2 140 tokens
€0.00033
13:02:09
whisper-large-v3-turbo
transcriber
4.0 min
€0.00062
13:01:58
qwen3-embedding-8b
support-agent
18 400 tokens
€0.00014
13:01:40
deepseek-ocr-2
ocr-batch
7 110 tokens
€0.00016
13:01:12
flux-2-klein
image-studio
1 image
€0.00132
Illustrative console view. Example requests, priced at the From prices of the catalogue (2026-10-22).
Model inference on Shadow-operated GPUs runs in Europe. Optional web search uses Staan. Check the data-handling details for model requests and external tools.
FAQs
Is it really the OpenAI API?
Models is OpenAI-compatible. Point the OpenAI SDK you already use at Blade’s base URL, set your Blade key, and keep your code.
Why does the rate change during the day?
Dynamic rates follow GPU demand. The multiplier in force when you submit a request is the one used for it, and each model publishes a From price: the lowest its rate can reach. How hourly pricing works.


 Flash by Staan to get answers with cited sources. Available on enabled accounts and supported models.