 blade
Get your API key
Serverless GPU compute Opening gradually
Your Python.
Our GPU fleet.
Bring your model, a Python batch job or an agent workload. Join the waitlist to choose a runtime, size the GPU and prepare deployment with the team.
Join the waitlistA Python workload to bring.
def transcribe(url: str):
    return model.transcribe(url)
Illustrative function using your own loaded model. SDK setup, deployment commands and GPU access are provided during onboarding.
Deploy models
from Python.
Prepare a small workload first.
Complete deployment with the access provided during onboarding.
- 01
Write the function.
Keep the model, dependencies and representative input together.
predict.py + requirements.txt - 02
Set up with the team.
Confirm the runtime, GPU memory and deployment interface for your workload.
Runtime + GPU + access - 03
Test the deployment.
Check outputs, startup time and concurrency before connecting production traffic.
Python → GPU → URL
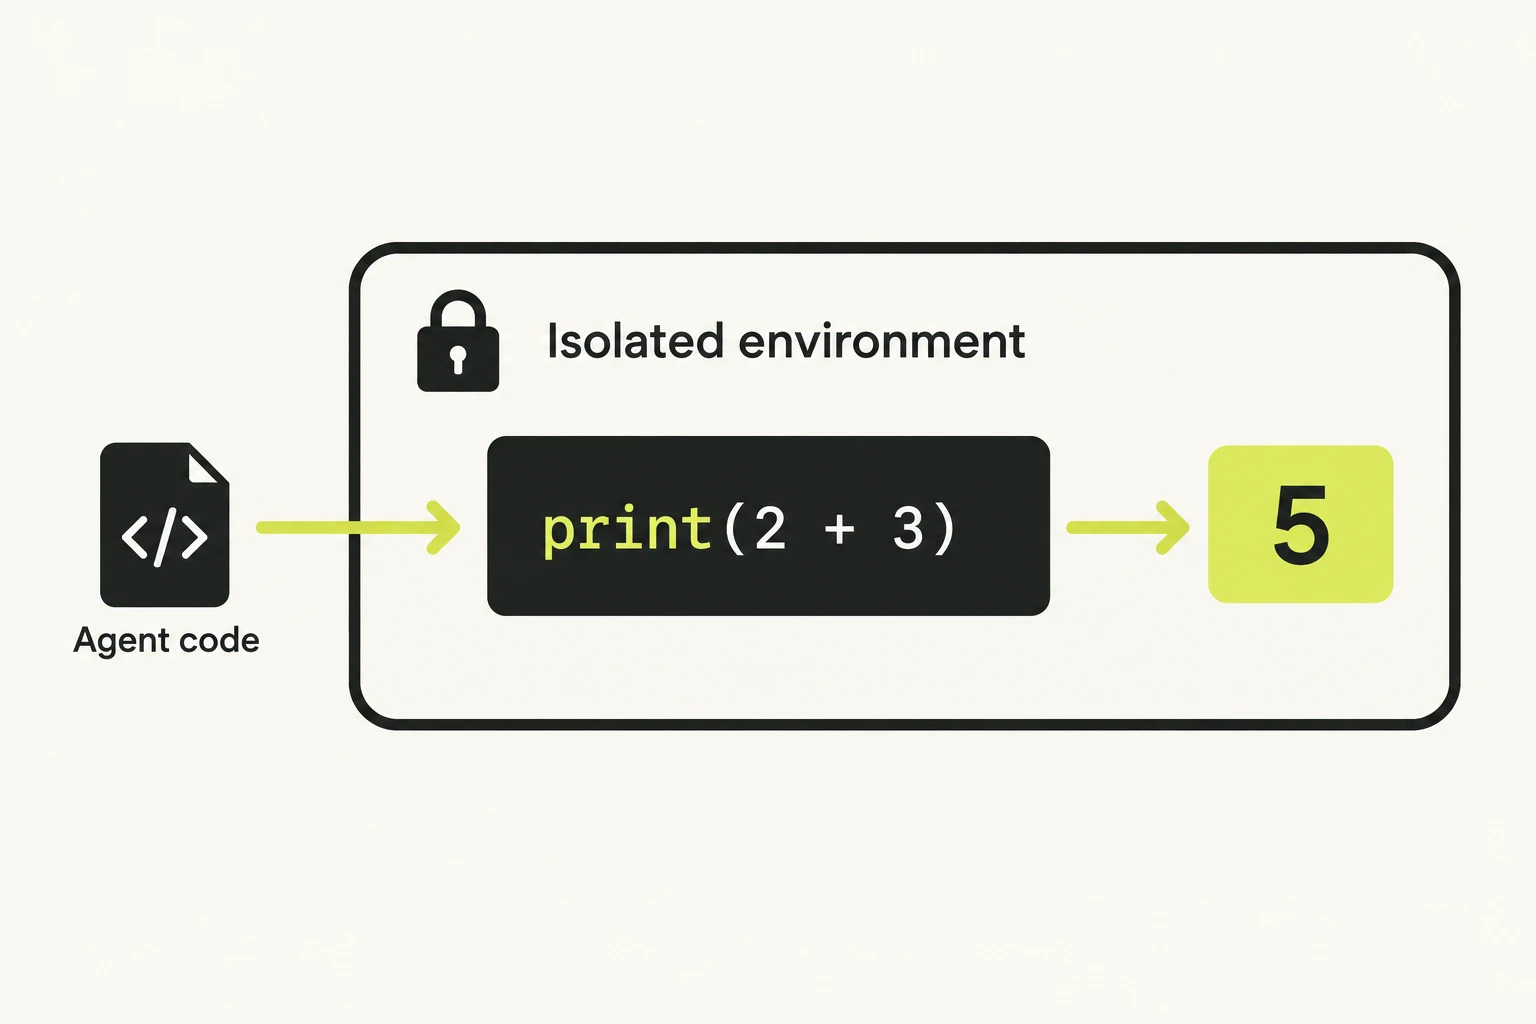
Concept: an isolated environment for agent code.
Run the work
behind your app.
Bring the workflow you need. Confirm its runtime and execution controls during onboarding.
- Serve your own model.
- Put inference behind an HTTP endpoint.
- Process a batch.
- Run document pipelines and batch jobs over many inputs.
- Run on a schedule.
- Make recurring work part of the same Python project.
- Give agents a sandbox.
- Execute generated code in an isolated environment.
Work comes and goes.
Your GPUs should too.
Serverless is designed around autoscaling and scale to zero. Confirm startup behaviour, idle settings and the billing unit for your workload during onboarding.
Available scaling settings and commercial terms are confirmed with your access.